s = 'some text'5 Working with Text
ImportantLearning Outcomes for this Lesson
Upon completion of this lesson you should:
- …know when and how to convert numerical data to and from strings
- …be able to perform operations to manipulate strings
- …know how to format strings to get desired output
- …be able to use f-strings to insert values into strings
- …know how to write multiline strings
- …know how string comparisons work
re included in the standard library. Regex is outside the scope of this class, but it’s worth logging it’s existence in the back of your mind for some future use case.
5.1 Creating Strings
NoteVideo: Strings and quotation marks
Socratica · about 3 min. Create strings with single, double, and triple quotes, and handle quotation marks inside text with escape characters.
We can create a variable containing text in the same way we assign a number:
We can also convert numerical data to string format:
number = str(11/7)
print("Result:", number)
Result: 1.5714285714285714Note that the evaluation of 11/7 occurs before the string conversion occurs.
NoteThe
input function is rarely used
In addition to assigning values using normal assignment statements, it is also possible to ask the user for some text input using the following built-in function:
s = input()This features is rarely used in scientific Python code. However, it is often used in “utility” apps, also known as “command-line interface” tools (CLI), that do things like delete duplicate photos or upload files. Theses types of programs will often ask “Are you sure (y/n)”, which indicates that your two options are “y” and “n” (for yes and no, obviously).
5.2 Manipulating Strings
5.2.1 Strings are Containers
Strings are sequences of Unicode characters. Indexing works much like it does for lists, but the result of indexing a string is another string of length 1.
For instance, subsets of strings can be accessed by index:
s = 'this is a string'
print(s[0])tOr:
s = 'this is a string'
print(s[0:4])thisOr:
s = 'this is a string'
print(s[5:7])isStrings are immutable, like tuples: you cannot replace a character using indexed assignment. String transformation methods return a result without changing the original string. Reassign the variable if you want it to refer to that result.
5.2.2 Operations on Strings
As has been pointed out already, the reason Python insists on everything having a type is so that is knows how to perform operations on them.
The + symbol is a very useful example of this. When placed between two ints like 1 + 3, we know that + means addition in the mathematical sense. However, when placed between two strs like 'taylor' + 'travis' we also know this means join in the physical sense.
Sure enough:
'taylor' + 'travis''taylortravis'This is called concatenation.
We can use other operators on strings too:
'Nom'*5'NomNomNomNomNom''worries'*0''Note that - and / don’t work, which also agrees with our understanding of operations you can do to text.
5.2.3 Using the String Object’s Methods
NoteVideo: String methods
Bro Code · about 5 min. Try common string methods for changing case, finding characters, and checking what a string contains.
Built-in functions such as sorted() and len() work on strings. A str object also supplies methods for searching and transforming text. Transformation methods return strings; they do not alter the original. Other methods can return different types, such as a list from split() or a Boolean from endswith().
str object. For a complete list see Table A.6.
| Method | Description |
|---|---|
capitalize() |
Returns a copy with the first character titlecased and the remaining characters lowercased |
count() |
Returns the number of times a specified value occurs in a string |
endswith() |
Returns True if the string ends with the specified value |
find() |
Returns the first index of a substring, or -1 if it is absent |
join() |
Joins an iterable of strings using this string as the separator; non-string items raise TypeError |
lower() |
Converts a string into lower case |
replace() |
Returns a string where a specified value is replaced with a specified value |
split() |
Returns a list of pieces split at a separator; with no argument, splits on runs of whitespace |
startswith() |
Returns True if the string starts with the specified value |
upper() |
Converts a string into upper case |
zfill(width) |
Pads with ASCII zeros to a total width, after any leading + or -; does not shorten longer strings |
Several of these methods are especially useful. For instance, the replace() method can be used to replace any characters which are causing problems.
For instance, perhaps we want to replace a tab character (written \t in a string literal) with a comma:
s = '123\t456'
changed = s.replace('\t', ',')
print(s)
print(changed)
123 456
123,456The original s still contains the tab. Writing s = s.replace('\t', ',') would reassign s to the returned string.
Another useful tool is split(), which will turn a single string into multiple strings by splitting it at the given character:
s = 'filename.txt'
s = s.split('.')
print(s)
['filename', 'txt']5.2.4 Joining Multiple Strings into a Single String
NoteVideo: Splitting and joining text
Real Python · about 5 min. Focus on split(): turn text into a list of pieces using whitespace or a chosen separator. Compare this with join() in the examples here.
We have seen that Python will interpret operators like + differently depending on data type. We can join two strings using:
a = 'Hello'
b = 'World'
c = a + ' ' + b
print(c)
Hello WorldIt is common to have many strings that need to be “joined”. We could do it the verbose way:
- 1
-
Each word is an item in a
list - 2
-
We need to initialize an empty
stringso we have something to add to - 3
-
itemwill take on each values in the list - 4
-
The first item has no separator before it; later items have one space.
repr()displays the string with quotes so a leading or trailing space would be visible.
'this is a list of several strings'But because it is so common Python has a shortcut for us. The join method on a string object accepts a list of strings as follows:
strings = ['this', 'is', 'a', 'list', 'of', 'several', 'strings']
1new_string = ' '.join(strings)
print(repr(new_string))- 1
-
' 'is a one-space separator, not an empty string or an accumulator. Itsjoin()method inserts that separator between successive strings, with no extra separator at either end.''.join(strings)would join them without spaces. Both versions also work for an empty list, producing''.
'this is a list of several strings'We can convert a string to a list, then we can use indexing to change specific characters, then use the join() method to convert back:
- 1
-
Converting a string to a list puts each character as a separate entry in the list.
- 2
-
We can then change any character as needed.
- 3
-
Converting back to a string is a bit tricky though. We can’t just use
str(s2). We must use thejoin()method to “join” each character in thelistback into a string.
['t', 'h', 'i', 's', ' ', 'i', 's', ' ', 'a', ' ', 's', 't', 'r', 'i', 'n', 'g']
this was a string
Another very common situation is to separate a sentence into separate words. We can use the split() method for this, which returns a list with each word as a separate item.
s = 'this is a sentence'
1s2 = s.split(' ')
print(s2)- 1
- We can specify a character or a longer string as the separator. Here a single space separates each word in the sample sentence.
['this', 'is', 'a', 'sentence']An explicit separator is matched as a whole string, not as a set of individual characters. Repeated spaces create empty items with split(' '), whereas split() groups whitespace such as spaces, tabs, and newlines and omits empty items at the ends:
text = '  this\tis  a sentence  '
print(text.split(' '))
print(text.split())
['', '', 'this\tis', '', 'a', 'sentence', '', '']
['this', 'is', 'a', 'sentence']And we can use the join() method to put them all back together once we’re done:
- 1
-
We need to catch the result of the
split()method in a new variable. - 2
-
s2is a list already, with each word as an item, so we can uselistmethods; in this case we usedinsert()to insert a new word. - 3
-
We can use the
join()method to put things back into a sentence.
this is a short sentence5.2.5 Converting Strings to Other Types
It may seem a bit silly to convert 1.0 to '1.0' and back, but this is actually extremely common when reading and writing files. We will talk about reading and writing files later in the course, but the main issue is that we simple humans require files that are human readable, while computers prefer other more efficient formats. “Human readable” basically means a file filled with text. For this reason we need to convert all numerical values to str before writing to a file that is intended to be human readable, and vice versa.
The following code will not work:
number_of_cookies = 3
message = "There are " + number_of_cookies + " cookies."
Why not? Because you cannot add a string and a numerical value. Instead we must do:
number_of_cookies = 3
message = "There are " + str(number_of_cookies) + " cookies."
print(message)
There are 3 cookies.And of course we can convert in the reverse direction too:
input_string = "4.56893"
input_value = float(input_string)
print("Result:", input_value)
Result: 4.56893input() and files opened in text mode provide strings, so numerical input must be converted before arithmetic. The text must be eligible for the requested conversion: int('a') and int('2.0') raise ValueError, while float('2.0') succeeds.
5.2.6 Escape Characters
One very common task is writing data to a file, and a common subset of this task is writing tabular data, like:
| Time | Temperature | Humidity |
|---|---|---|
| 13:31.04 | 29.1 | 55 |
| 14:29.11 | 28.2 | 56 |
| 15:30.40 | 28.5 | 54 |
To make our file “human readable” we would insert “tabs” (or spaces, or commas) between values, and “new lines” after each row is complete. Python does not do this for us by default, so we need to insert some “markers” into the text. These are:
\nfor a new line\tfor a tab
The appearance of a \ tells Python that the next character is special. This \ is called an escape character because it tells Python to “escape” the act of reading the text as pure text.
This presents a small conundrum though: how to you put an actual
\ in the text? You escape it with \\!One more source of trouble comes from the use of ' and ". If you start your string with ', then Python will end the string when it sees the next '. If you want to use ' in your text then you have two options:
- You can start your string with
", then you can use all the'you like (and vice versa) - You can escape the
'with\'.
| Escape Sequence | Effect |
|---|---|
\' |
A single quote |
\" |
A double quote |
\\ |
A backslash |
\n |
A new line |
\t |
A tab |
5.2.7 Inserting Values Into Strings
NoteVideo: Formatting values in f-strings
Bro Code · about 5 min. Format values inside f-strings with decimal precision, padding, alignment, and thousands separators.
Printing text that contains the value of variables is so common that Python has a shortcut for this. It is called an f-string.
print(f"The value is {11/7}")The value is 1.5714285714285714The above line has several crucial features:
- The string is prefaced with an ‘f’ which tells Python this string is to given special treatment.
- The curly braces inside the f-string tells Python where active code is located. It will evaluate these expressions, and there can be more than one.
- We did not need to convert the results of
11/7to a string, as Python knows this is already inside a string so does it for us.
The output of numerical value when written to text can often be ugly (i.e. way too many decimal places). Since this is such a common task, Python offers a way to control the conversion.
print(f"The value is {11/7:.2f}")The value is 1.57Here we have followed our value (11/7) with a :, then .2f, meaning “format this value in fixed-point notation with 2 decimal places”. This controls the resulting text; it does not change the stored number or convert it to a different numerical type.
You can also have values written in scientific notation:
print(f"The value is {1111/7:.2e}")The value is 1.59e+02Table Table 5.3 gives examples of different types of output and how to get it. Assign the number in the first column to x, then evaluate the f-string shown.
| Number | F-string | Output | Description |
|---|---|---|---|
| 3.1415926 | f"{x:.2f}" |
3.14 | Fixed-point, 2 decimal places |
| 3.1415926 | f"{x:+.2f}" |
+3.14 | Fixed-point, 2 decimal places with sign |
| -1 | f"{x:+.2f}" |
-1.00 | Fixed-point, 2 decimal places with sign |
| 2.71828 | f"{x:.0f}" |
3 | Fixed-point, no decimal places |
| 5 | f"{x:0>2d}" |
05 | Pad integer with zeros (left padding, width 2) |
| 5 | f"{x:x<4d}" |
5xxx | Pad integer with x’s (right padding, width 4) |
| 1000000 | f"{x:,}" |
1,000,000 | Number format with comma separator |
| 0.25 | f"{x:.2%}" |
25.00% | Format percentage |
| 1000000000 | f"{x:.2e}" |
1.00e+09 | Exponent notation |
And “f-strings” work with variables as well!
pi = 3.14159
print(f"The value of pi is {pi}")
The value of pi is 3.14159And of course we can do operations on variables:
pi = 3.14159
D = 1.5
print(f"The area of a circle with a diameter of {D} is {pi/4*D**2}")
The area of a circle with a diameter of 1.5 is 1.767144375
NoteBefore
f-strings was format
“f-strings” were added to Python fairly recently and are a huge timesaver. The previous way to insert values into strings was verbose and hard to read:
print("The value is {a}".format(a=11/7))The value is 1.5714285714285714Or we could include the decimal place formatting information:
print("The value is {a:.2e}".format(a=11/7))The value is 1.57e+00And multiple variables were handled as:
pi = 3.14159
D = 1.5
print("The area of a circle with a diameter of {a} is {b:.2f}".format(a=D, b=pi/4*D**2))
The area of a circle with a diameter of 1.5 is 1.77The introduction of “f-strings” was obviously very welcome! However, you will still often see code that uses the format() style, since it still works just fine and people are either:
- used to the old approach so stick with it
- too busy to find the time to update old code
5.3 Multiline Strings
To write long strings which span multiple lines we could write each line as a separate string and join them using +, as follows:
s = ("this \n"
    + "text \n"
    + "spans \n"
    + "multiple \n"
    + "lines \n")
print(s)
this
text
spans
multiple
lines
but this is rather tedious. Instead we can put out text between triple quotes and write as many lines between them as we wish:
s = """
This
text
spans
multiple
lines
"""
print(s)
This
text
spans
multiple
lines
If we inspect s we’ll find that \n has been inserted for us: '\nThis\ntext\nspans\nmultiple\nlines\n'
5.4 Comparing Strings
Relational operators can also compare strings. Python uses lexicographic ordering: it compares corresponding characters by their Unicode code points, and the first difference determines the order. This often resembles alphabetical order for simple English text, but it is not a language-aware dictionary ordering.
'Fred' < 'Harry'True'Fred' < 'Fanny'FalseCase matters. For the ASCII letters A–Z and a–z, uppercase letters precede lowercase letters:
'A' < 'a'TrueComparisons are evaluated character by character:
'abc' < 'abd'TrueDigits inside strings are compared as characters, not as numerical values. This version-number comparison happens to give the expected result:
v1 = "3.11.3"
v2 = "3.12.1"
v1 < v2TrueBut plain string comparison is not a reliable way to compare software versions:
print("3.9.0" < "3.10.0") # False: '9' comes after '1'FalseComparing versions correctly requires parsing their components as numbers and following the version scheme’s rules; a version-handling library can do this for package versions.
When one string is a prefix of another, the shorter string comes first:
'abc' < 'abcd'TruePython also provides functionality to search for a string withing another string using the in operator:
'abc' in 'abcd'True'acb' in 'abcd'FalseThe empty string is always a substring of another string:
'' in 'abc'TrueThe list of string methods also contains some tools for comparison. For instance, endswith and startswith are useful:
- 1
- The nice thing about this method is that we don’t need to worry about the length of the text we’re looking for.
- 2
- A conditional expression chooses the text describing the suffix check.
- 3
-
The f-string includes the queried text and result. This is a case-sensitive suffix check, not email validation: even
'@uwaterloo.ca'passes, and the check does not establish whether an account exists.
email.address@uwaterloo.ca matches the UW email suffixExample 5.1 (Use Dictionary Keys to Identify Data) Storing data in “Excel Sheets” is exceedingly common. The top row of each column is often the “header” which indicates the data stored there, while each row is a new data point. A typical example is weather data. The University of Waterloo maintains a weather station on campus, and the historical data back to 1998 is available here. The data is reported in a format like that shown below.
| year | m | d | hr | min | Temp | RH | Pressure |
|---|---|---|---|---|---|---|---|
| 2023 | 1 | 1 | 0 | 0 | -1.43133 | 90.53333 | 101.62801 |
| 2023 | 1 | 1 | 0 | 15 | -1.43133 | 90.53333 | 101.62801 |
| 2023 | 1 | 1 | 0 | 30 | -1.55 | 90.53333 | 101.628 |
| 2023 | 1 | 1 | 0 | 45 | -1.616 | 90.5 | 101.63467 |
| 2023 | 1 | 1 | 1 | 0 | -1.616 | 90.5 | 101.64334 |
| 2023 | 1 | 1 | 1 | 15 | -1.668 | 90.5 | 101.65135 |
| 2023 | 1 | 1 | 1 | 30 | -1.79867 | 90.5 | 101.66534 |
| 2023 | 1 | 1 | 1 | 45 | -1.91 | 90.48 | 101.67735 |
Tidy up the column names by giving them consistent case and adding units: temperature in °C, relative humidity in %, and pressure in kPa. Also, add a column for time elapsed since the start of the year (in minutes) so the trends can be plotted against time.
Solution
A dictionary with one list per column is a convenient way to represent this tabular data using the tools we know so far:
data = {
    'y': [2023, 2023, 2023, 2023, 2023, 2023, 2023, 2023],
    'm': [1, 1, 1, 1, 1, 1, 1, 1],
    'd': [1, 1, 1, 1, 1, 1, 1, 1],
    'h': [0, 0, 0, 0, 1, 1, 1, 1],
    'min': [0, 15, 30, 45, 0, 15, 30, 45],
    'Temperature': [-1.43133, -1.43133, -1.55, -1.616,
                    -1.616, -1.668, -1.79867, -1.91],
    'RH': [90.53333, 90.53333, 90.53333, 90.5,
           90.5, 90.5, 90.5, 90.48],
    'Pressure': [101.62801, 101.62801, 101.628, 101.63467,
                 101.64334, 101.65135, 101.66534, 101.67735],
}
We can use the keys() method to ensure that everything is present:
for key in data.keys():
    print(key)
y
m
d
h
min
Temperature
RH
PressureLet’s start by correcting the case. We’ll do it ‘programmatically’ (i.e use Python to do it inside a loop instead of doing it by hand):
new_data = {}
for k in data.keys():
    new_data[k.lower()] = data[k]
Now add the units to the measurement keys. pop() returns each column and removes its old key:
new_data['temperature [°C]'] = new_data.pop('temperature')
new_data['relative humidity [%]'] = new_data.pop('rh')
new_data['pressure [kPa]'] = new_data.pop('pressure')
for key in new_data.keys():
    print(key)
y
m
d
h
min
temperature [°C]
relative humidity [%]
pressure [kPa]Now let’s create a new column which contains the time in minutes since the start of the year:
- 1
- Initialize a counter which will be incremented
- 2
-
Initialize an empty
listto which each new cumulative_time will be added - 3
- We need to add the time to the list first, then increment it, otherwise our first time will be 15.
- 4
-
After we’re done we add it to the cleaned
new_datadictionary
[0, 15, 30, 45, 60, 75, 90, 105]
Caution
It is worth pointing out that our total_time calculation is a bit naive. We assumed each row was 15 minutes apart in time, but what happens if a row is missing? We should have used a more robust logic to determine how much actual time had elapsed between rows
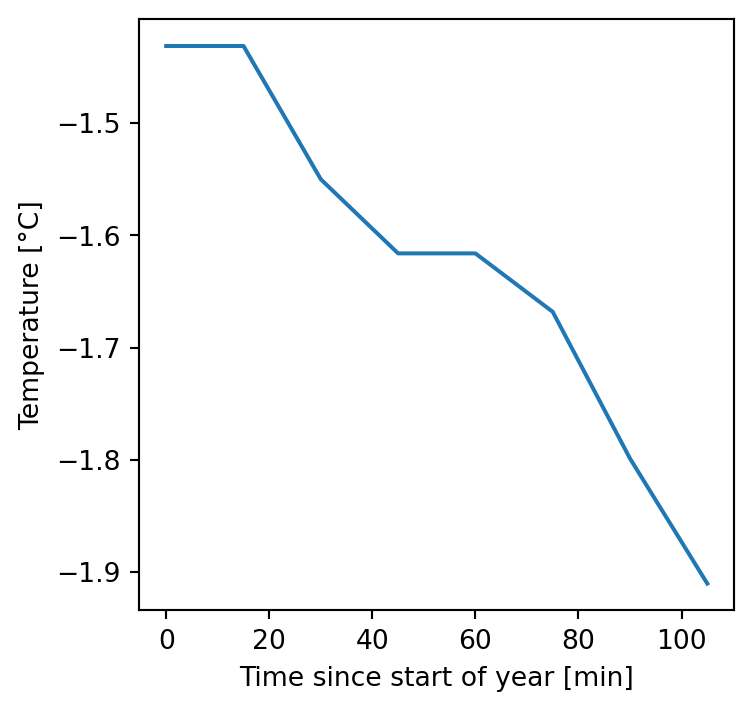
Finally, we can plot the result using matplotlib, which we’ll learn about after the midterm:
import matplotlib.pyplot as plt
fig, ax = plt.subplots(figsize=[4, 4])
1ax.plot(new_data['total_time [min]'], new_data['temperature [°C]'])
ax.set_xlabel('Time since start of year [min]')
ax.set_ylabel('Temperature [°C]')- 1
-
I am trying very hard to resist the urge to format this plot in a more professional manner since I don’t want to confuse things on your first introduction to
matplotlib. But in a few weeks we’ll do a deep dive into how to make these plots look great!
Comments
“Massaging” data like this is a very common task in all aspects of engineering. Data comes from many diverse sources, each with their own styles, formats, conventions, etc. The field of machine learning for instance, is mostly about collecting and organizing data. The actual “training” of the AI to learn from the data is almost a blackbox at this point.
TipChanging a
dict while iterating over it
Changing a dictionary’s keys while iterating over its live keys view can raise RuntimeError or cause entries to be missed. This standalone example illustrates the problem; it is not a step in the main weather solution:
example = {'Temperature': [20.0], 'RH': [50.0]}
for k in example.keys():
1 example[k.lower()] = example.pop(k)- 1
- Removing and adding keys invalidates the live iteration, even if the dictionary ends each iteration with the same number of entries.
Instead, iterate over a separate list of the original keys. Here the new names are distinct, so renaming cannot overwrite another column:
example = {'Temperature': [20.0], 'RH': [50.0]}
1for k in list(example.keys()):
    example[k.lower()] = example.pop(k)
print(example)- 1
-
The separate list of keys is unaffected by changes to
example. Neitherdatanornew_datais modified by this optional example.
{'temperature': [20.0], 'rh': [50.0]}5.5 Assignment 4
Submit one Jupyter notebook named A4.ipynb. Use one code cell for each question. The first non-blank line in each cell must be the indicated tag, such as # A4Q1. Each question below gives its required cell tag. The checker supplies fresh input values each time it runs a cell and checks the value assigned to answer.
The tables show example inputs and the expected value of answer. A result such as False or [] is a valid answer, not an error. Where a row says Raises, your code must raise the indicated exception instead of assigning an answer. Except for the invalid inputs explicitly described below, you may assume the inputs have the stated types and formats.
NoteQuestion 1: Count letters in a string
The checker provides a string as value. Count its uppercase and lowercase letters and assign the count to answer.
Cell tag: # A4Q1
value |
Expected answer |
|---|---|
"Hello!" |
5 |
"Room 204" |
4 |
"123 !?" |
0 |
"" |
0 |
NoteQuestion 2: Count non-space characters
The checker provides a string as value. Count all characters except spaces and assign the count to answer. Exclude only ordinary spaces (' '); punctuation, digits, tabs, and newlines count as characters. If value is not a string, raise TypeError or AttributeError.
Cell tag: # A4Q2
value |
Expected answer or error |
|---|---|
"Hi, world! 123" |
12 |
"a\tb" (contains a tab) |
3 |
" " |
0 |
"" |
0 |
42 |
Raises TypeError or AttributeError |
NoteQuestion 3: Validate a password
The checker provides a password as password. Assign True to answer only when it contains at least one uppercase letter, lowercase letter, digit, and one of these special characters: !@#$%^&.
Cell tag: # A4Q3
password |
Expected answer |
Explanation |
|---|---|---|
"River7!" |
True |
Contains all four required character categories |
"river7!" |
False |
No uppercase letter |
"RIVER7!" |
False |
No lowercase letter |
"River!" |
False |
No digit |
"River7" |
False |
No special character |
"River7?" |
False |
? is not one of the allowed special characters |
NoteQuestion 4: Check an email domain
The checker provides email and domain. Assign True to answer when the email ends with the specified domain; otherwise assign False.
Cell tag: # A4Q4
email |
domain |
Expected answer |
|---|---|---|
"alex@example.org" |
"example.org" |
True |
"alex@example.org" |
"example.com" |
False |
"alex@example.org.backup" |
"example.org" |
False |
Compare the suffix exactly, including letter case; full email-address validation is not required.
NoteQuestion 5: Filter filenames by extension
The checker provides a list of filenames and an extension without its dot. Assign to answer a list containing only filenames with that extension.
Cell tag: # A4Q5
filenames |
extension |
Expected answer |
|---|---|---|
["notes.txt", "results.csv", "backup.csv"] |
"csv" |
["results.csv", "backup.csv"] |
["notes.txt", "results.csv"] |
"png" |
[] |
["results.csv.bak", "results.csv"] |
"csv" |
["results.csv"] |
[] |
"txt" |
[] |
Match the final extension exactly, including letter case, and preserve the order of matching filenames.
NoteQuestion 6: Compare two strings
The checker provides strings a and b. Assign the result of a < b to answer.
Cell tag: # A4Q6
a |
b |
Expected answer |
|---|---|---|
"apple" |
"banana" |
True |
"pear" |
"apple" |
False |
"same" |
"same" |
False |
"cat" |
"catalog" |
True |
NoteQuestion 7: Join a list of strings
The checker provides a list of strings as values. Join all values without an additional separator and assign the resulting string to answer. Preserve spaces already present in the strings. If any item is not a string, raise TypeError; do not convert that item to a string.
Cell tag: # A4Q7
values |
Expected answer or error |
|---|---|
["Hello", " ", "world!"] |
"Hello world!" |
["red", "blue"] |
"redblue" |
[] |
"" |
["Room ", 204] |
Raises TypeError |
NoteQuestion 8: Convert key-value text to a dictionary
The checker provides key-value text as value. Each pair has the form "key:value" and pairs are separated by semicolons. Assign the resulting dictionary to answer, keeping keys and values as strings. You may assume keys are unique and keys and values contain neither colons nor semicolons. If a pair does not contain exactly one colon, raise ValueError.
Cell tag: # A4Q8
value |
Expected answer or error |
|---|---|
"name:Alex;course:NE111" |
{"name": "Alex", "course": "NE111"} |
"count:12" |
{"count": "12"} (the value stays a string) |
"name=Alex;course:NE111" |
Raises ValueError |
"name:Alex,course:NE111" |
Raises ValueError (pairs must be separated by semicolons) |
NoteQuestion 9: Encrypt and decrypt messages
The checker provides message, number, and mode. When mode is "encrypt", insert number random letters after each letter in message. When mode is "decrypt", remove those inserted letters. Assign the resulting message to answer. You may assume message contains only letters, number is a non-negative integer, and mode is either "encrypt" or "decrypt". For decryption, the input follows the insertion pattern for the given number.
Cell tag: # A4Q9
message |
number |
mode |
Expected answer |
|---|---|---|---|
"Hi" |
2 |
"encrypt" |
For example, "HabixY"; random inserted letters will vary |
"HabixY" |
2 |
"decrypt" |
"Hi" |
"go" |
0 |
"encrypt" |
"go" |
"" |
2 |
"encrypt" |
"" |
Encryption must keep each original letter in place and insert exactly number letters after it. For the first example, "000000" has the right length but is an incorrect answer: it loses the original letters and inserts digits instead of letters. The original message unchanged is also incorrect when number is greater than zero.